PDFZora / Practical PDF guides
How to Use OCR to Make a Scanned PDF Searchable and Editable Online
Make scanned text easier to find, copy, and edit.
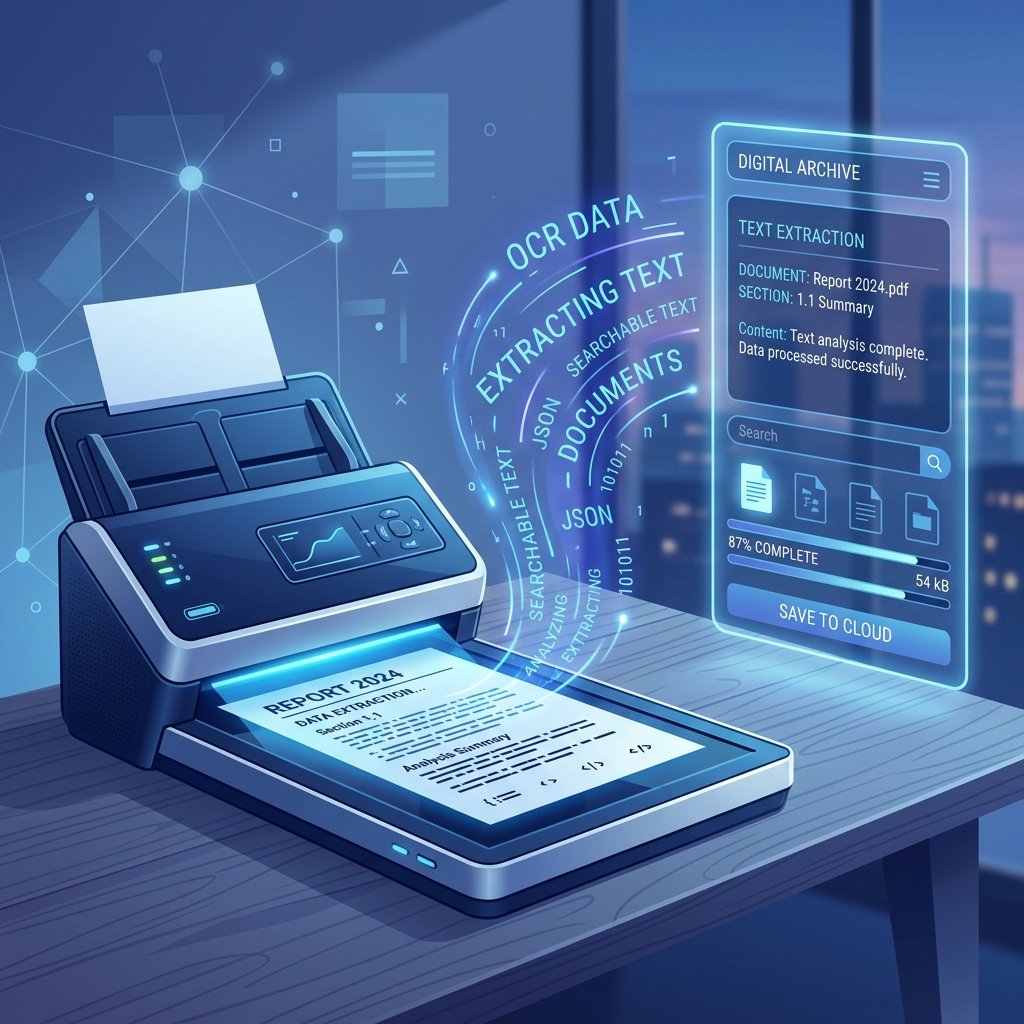


To make a scanned PDF searchable, run optical character recognition (OCR), save a PDF with a text layer, and test it with Ctrl+F or Command+F. To edit the wording, copy the recognized text into a document editor or use an OCR-enabled PDF-to-Word workflow. A searchable PDF does not automatically become a fully editable document.
A practical starting point
Make your scan searchable with PDFZora
PDFZora lists its OCR to PDF service as free to use without an account. Its stated output is a searchable PDF. Start with a short sample, then check that you can find and copy the text you need. For Word or TXT output, check whether your chosen converter supports that format.
Open OCR to PDF →Choose the output you need
If dragging across a sentence selects the whole page, your PDF may contain an image of the text. OCR recognizes characters in that image. The output you choose determines what you can do next.
These are different jobs. As the OCRmyPDF introduction explains, adding an OCR text layer makes scanned PDFs searchable. It does not recreate the original authoring file.
How to make a scanned PDF searchable, step by step
Keep the original and check the scan
Save a working copy before you begin. Open several pages, zoom in, and check that small characters are readable. Look for clipped margins, shadows, upside-down pages, or missing sheets. Try selecting a line first: some scanned PDFs already include OCR, so another recognition pass may be unnecessary.
Prepare a clear, upright document
Rotate sideways pages and straighten noticeably tilted scans. If you have the paper original, rescan blurry pages instead of repeatedly enlarging them. For a phone photo, flatten the paper, use even lighting, and keep the camera parallel to the page.
For Tesseract-based recognition, Tesseract’s image-quality guidance recommends at least 300 dpi and discusses skew and noise. Treat this as a useful scan setting, not a promise of perfect recognition or a universal minimum for every OCR tool.
Open an OCR tool and select your file
For PDFZora, follow the published upload, convert, and download sequence on its OCR to PDF page. Use the PDF selection control or drag-and-drop area if displayed. Begin with a short, non-sensitive sample so you can judge the result before processing a large document.
Before uploading confidential records, check your organization’s rules and the service’s current data-handling terms. If online processing is unsuitable, use an approved local OCR application.
Run recognition with appropriate settings
If your chosen application offers a language setting, select the language of the document. Select the required pages when a page-range control is available. Start recognition and wait for completion; the time depends on the document and the application.
For an alternative documented workflow, Adobe’s Acrobat instructions use All tools → Scan & OCR → In this file, followed by page-range and language settings and Recognize Text. Those controls describe Acrobat, not PDFZora.
Save and test the searchable PDF
Download the processed file under a clear name, such as
project-report-searchable.pdf. Reopen that downloaded copy in a PDF reader. Use Ctrl+F on Windows or Command+F on a Mac to search for a distinctive word that you can see on the page.Next, copy a paragraph into a plain-text editor. Check spelling, punctuation, and reading order. Test pages near the beginning, middle, and end; a successful search on one page does not confirm that the rest were recognized correctly.
Edit the text in the right format
For a short correction or quotation, paste the recognized text into Word or another editor and revise it there. For a longer document, use a converter that supports your OCR output and export to DOCX. Try a representative page first, especially if the document contains tables or columns.
Compare headings, lists, page breaks, and tables with the original scan. Text from separate columns may get mixed together, and table values may shift into the wrong rows or columns. Keep the source open beside the editable version while you correct it.
Common OCR problems and how to fix them
- Search returns nothing: confirm that you opened the processed download. Try a clearly printed word on another page. If none work, check that the application produced a text layer rather than another image-only PDF.
- Characters are wrong: improve the scan and check the recognition language when available. Pay particular attention to 0/O, 1/l, decimal points, reference numbers, and dates.
- Text copies in the wrong order: review columns separately. For tables, compare each row and heading with the scan before using the extracted values.
- The PDF is too large: keep an original-quality copy. If you compress the working file, reopen it and check both readability and search afterward.
Finish with a practical check: search for a heading, copy an ordinary paragraph, and verify an important number against the image. If the document will be shared, give the saved version a clear filename so readers can distinguish it from the unprocessed scan.
Searchable does not mean fully accessible
OCR provides real text, but an accessible PDF may also need tags, a logical reading order, headings, document language, and descriptions for meaningful images. The W3C technique for OCR in scanned PDFs includes checking the text and reading order. Do not label a document accessible solely because Ctrl+F works.
Frequently asked questions
1. Do I need to run OCR on every scanned PDF?
No. Some scanned PDFs already have a usable text layer. Try finding a visible word and copying a sentence first. If the file contains only page images, run OCR to recognize the words.
2. Will OCR let me edit the original page directly?
Not necessarily. A searchable PDF can retain its original image while adding selectable text. Editing the visible wording requires a suitable editor or conversion to an editable document format.
3. What if the PDF contains handwriting?
Check whether the application explicitly supports handwriting. Do not assume a tool intended for printed scans can read handwritten notes reliably. Test a representative page and review the result closely.
4. Can I use a phone photo instead of a scanner?
A clear, evenly lit photo can be a useful starting point if the tool accepts that file format. Keep all page edges visible and avoid glare. Check small text before running recognition.
5. Why are tables or columns scrambled?
Recognizing characters and reconstructing a layout are separate tasks. Copying or exporting can change reading order. Rebuild the table if needed, checking values against the original rather than trusting their new positions.
6. Should I compress the scan before OCR?
Avoid reducing image quality unnecessarily before recognition. Work from the clearest available scan. If you need a smaller final PDF, compress a copy afterward and test its text search and appearance again.
How to Use OCR to Make a Scanned PDF Searchable and Editable Online
Start with a clear scan and a short sample. After conversion, search for a word, copy a paragraph, and compare important numbers with the original before using the text.